Have dbt skills been bitter lesson’d?
 The grim reaper, labeled The Bitter Lesson, has already visited the doors marked Natural Language Processing and Prompt Engineering, and is now knocking on the door marked Skills
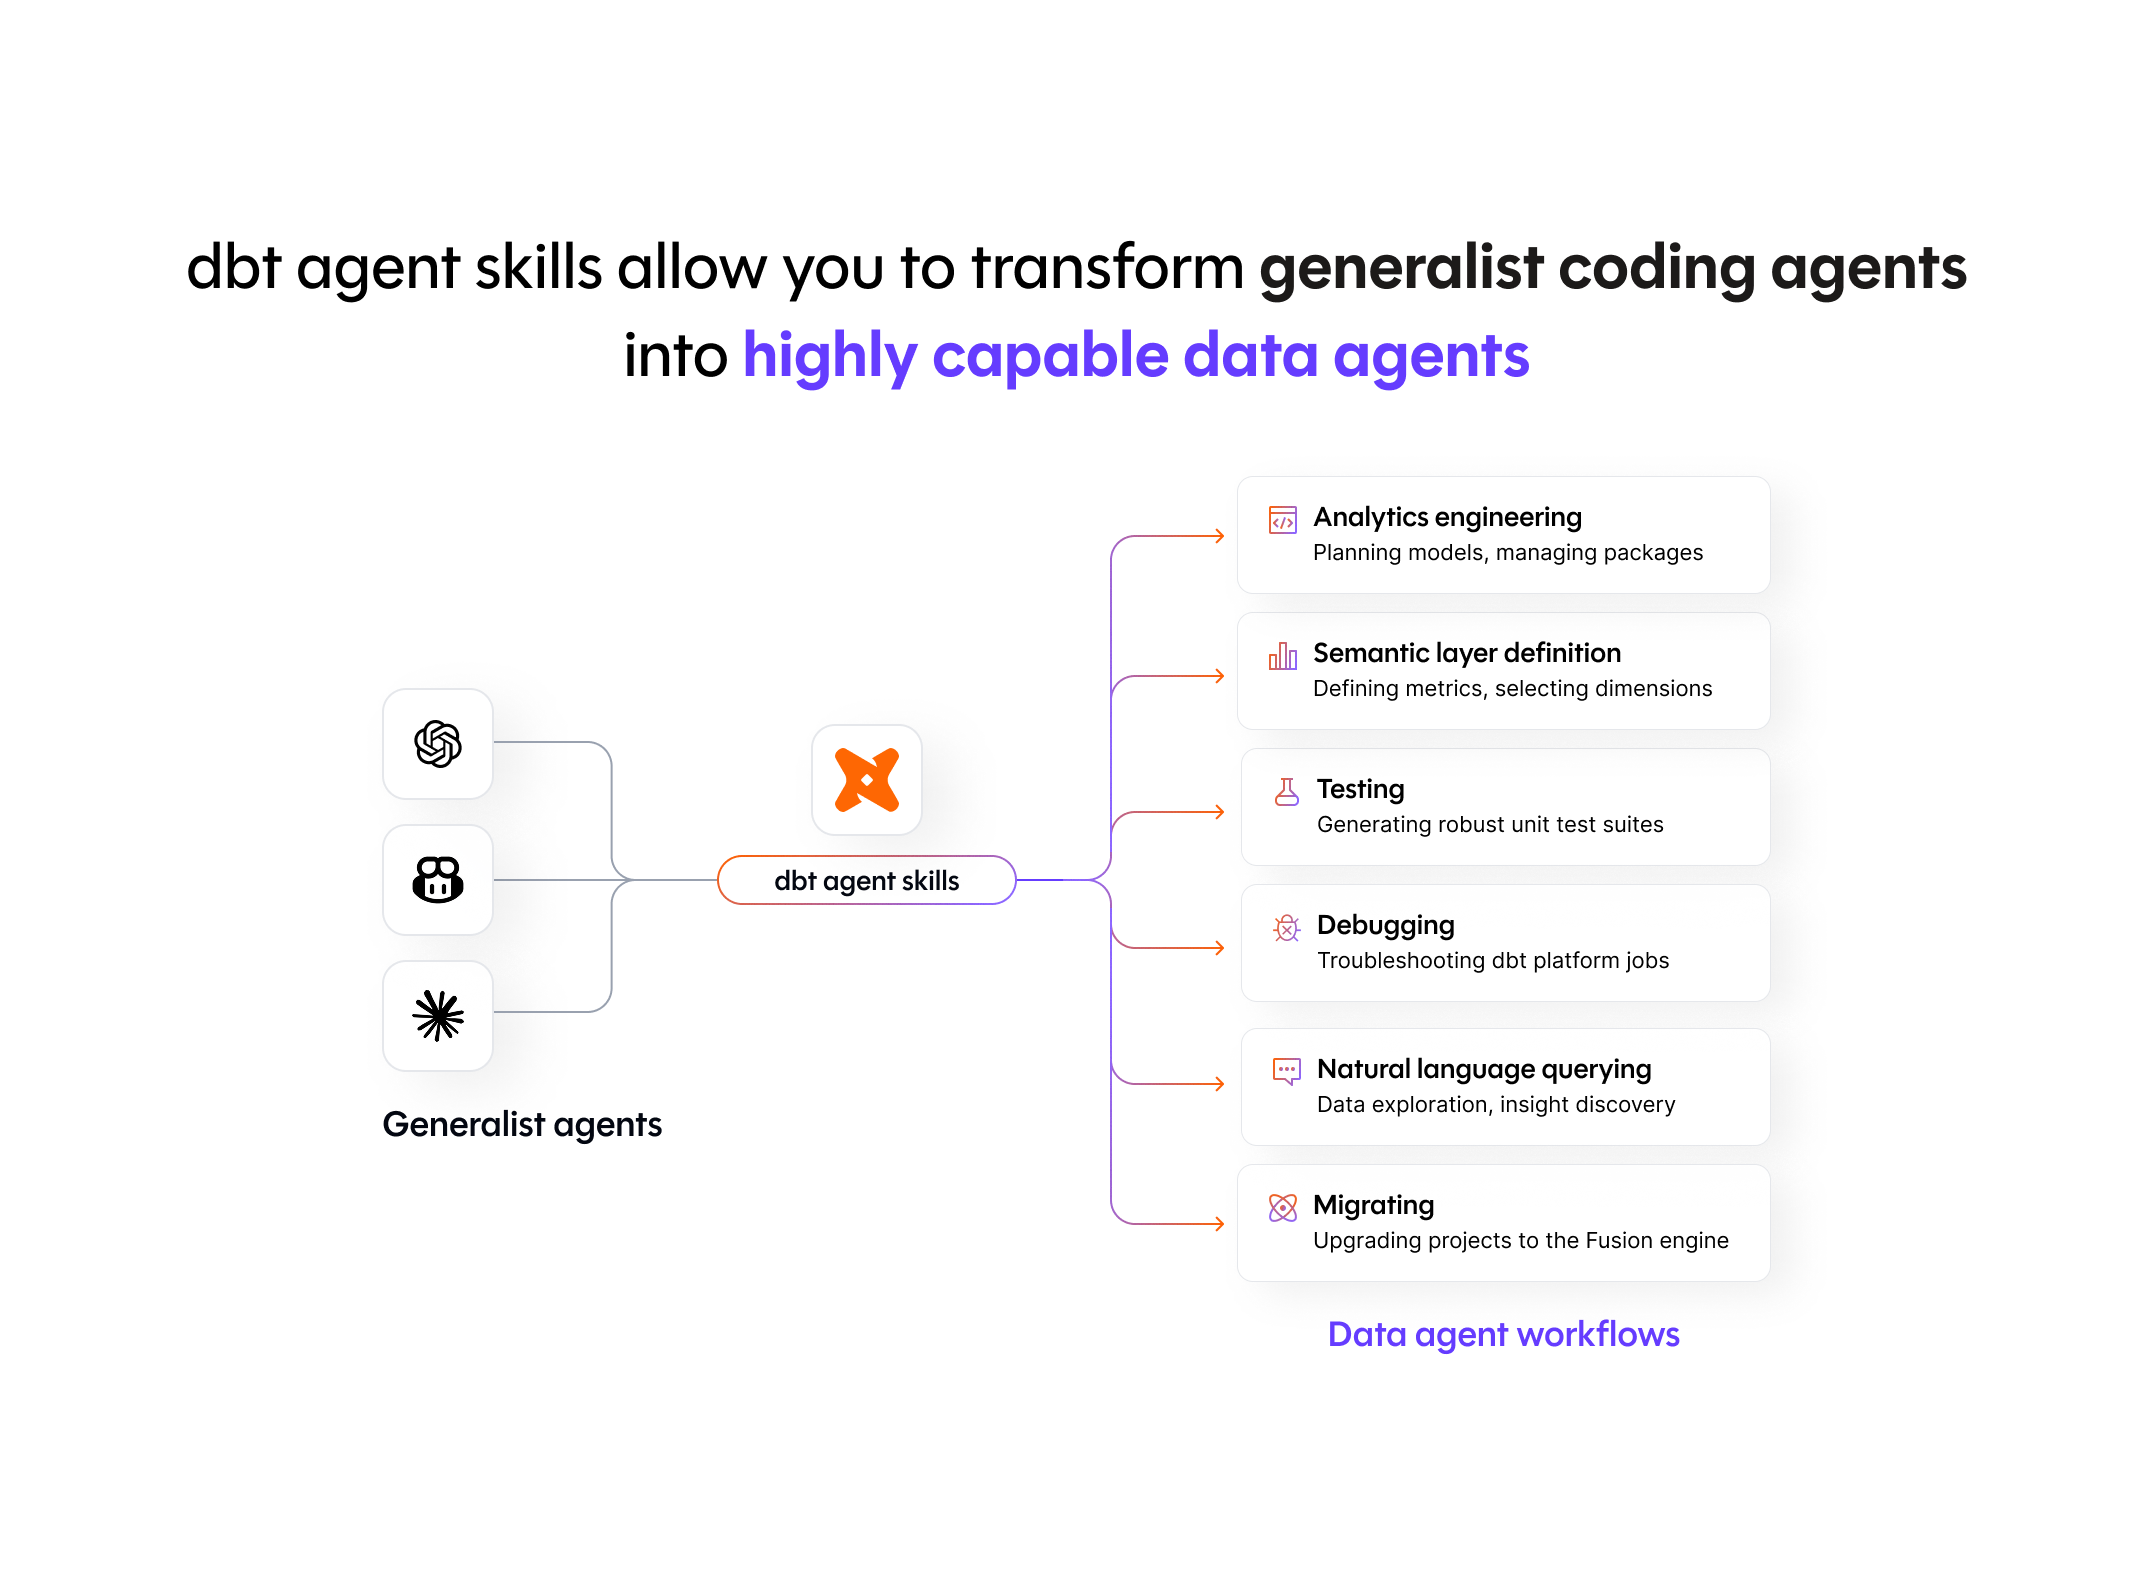
Do you remember what it was like trying to code with AI this time last year? The models could write SQL, but their judgment was poor. They skipped many of the signals of tradecraft that skilled analytics engineers have. Skills were the intuitive fix: give the agent the knowledge it needs for this task, without starting from zero every time or stuffing one AGENTS.md with everything that might come up. Skills arrived for Claude in October 2025 and became an open standard that December. We built our own set of dbt agent skills to give coding agents the conventions, commands, and patterns they were missing.
Models have improved a lot since then, and one must always remember the Bitter Lesson for AI, where being too clever is a losing strategy compared to just pointing more computing resources at the problem. So I wanted to check whether that bet still holds. Can the latest models build and maintain a dbt project at real-project scale without skills? And if they can, where do skills still earn their place?
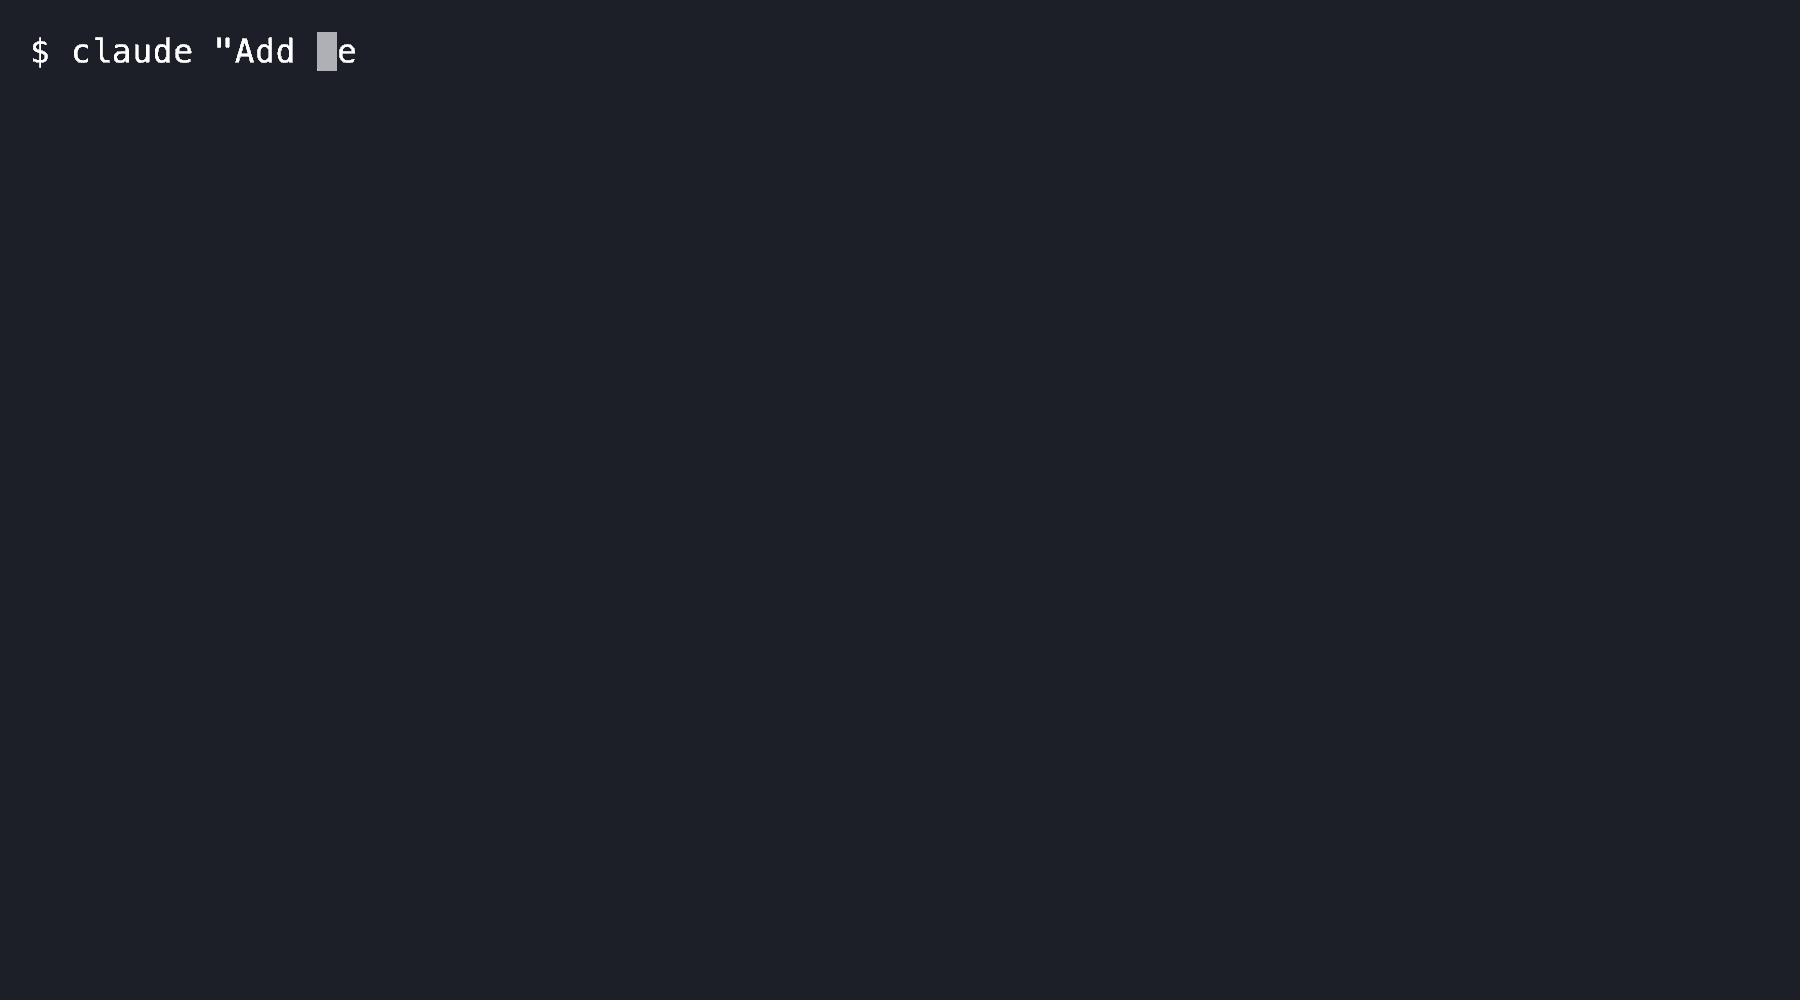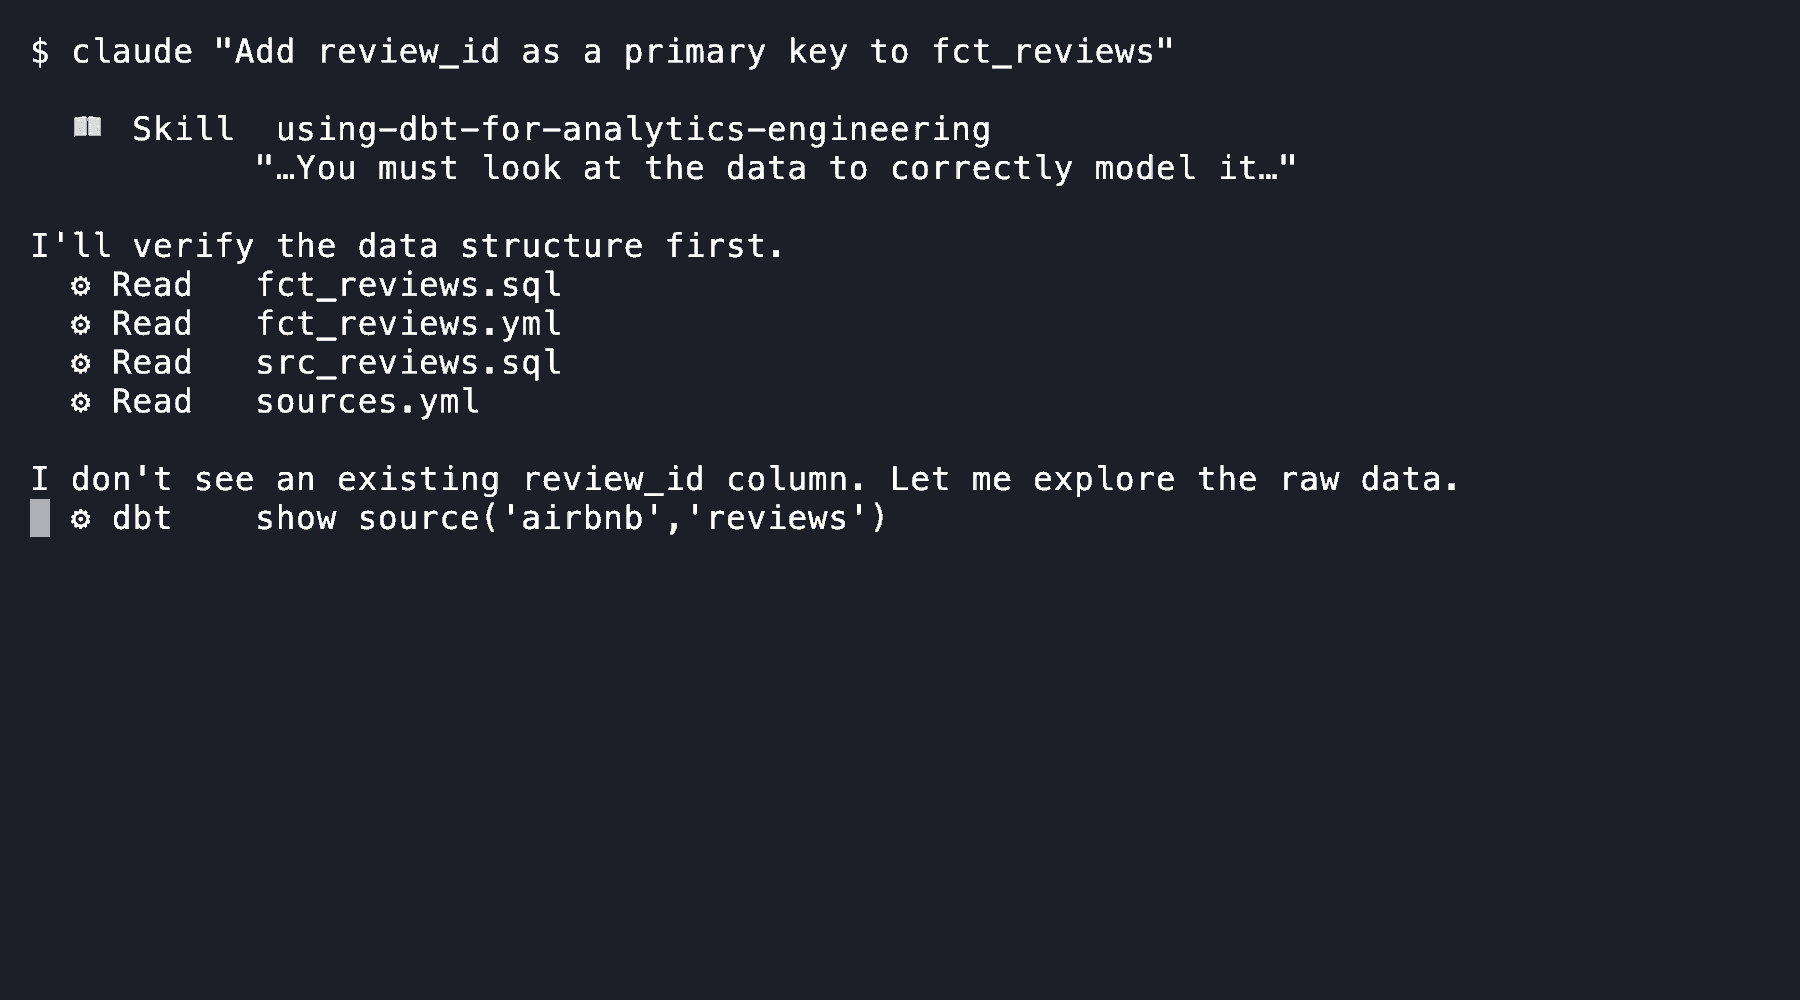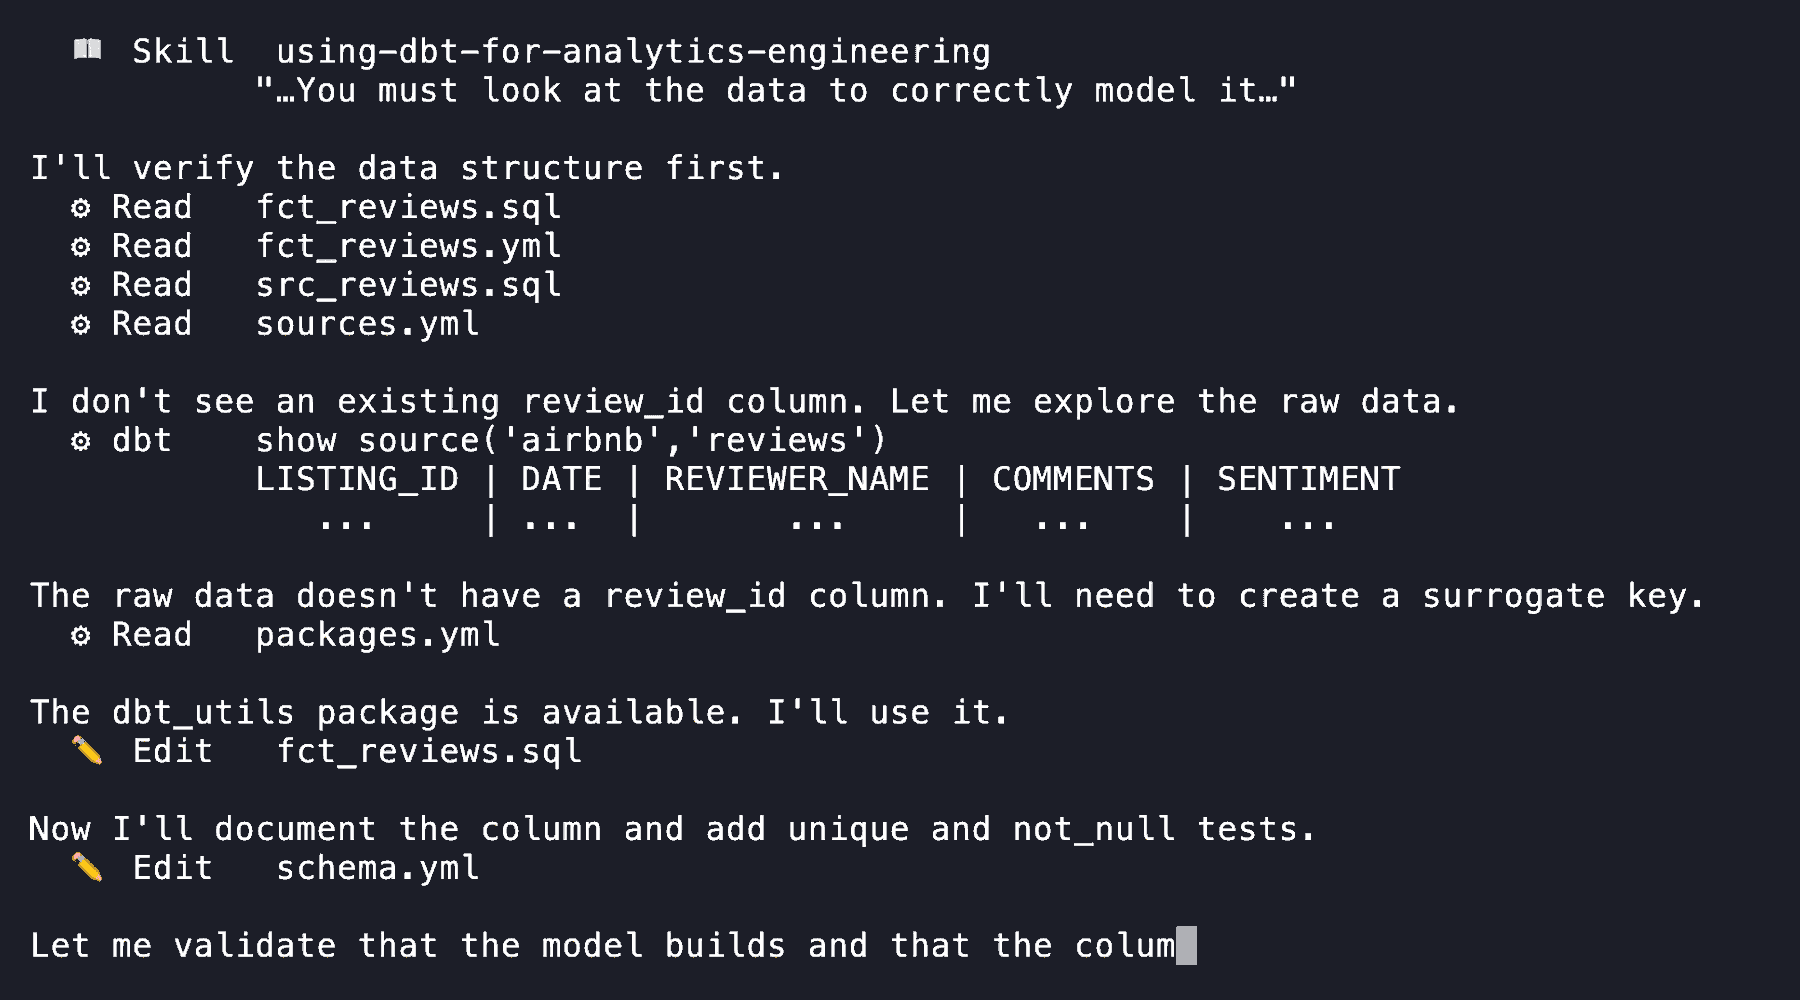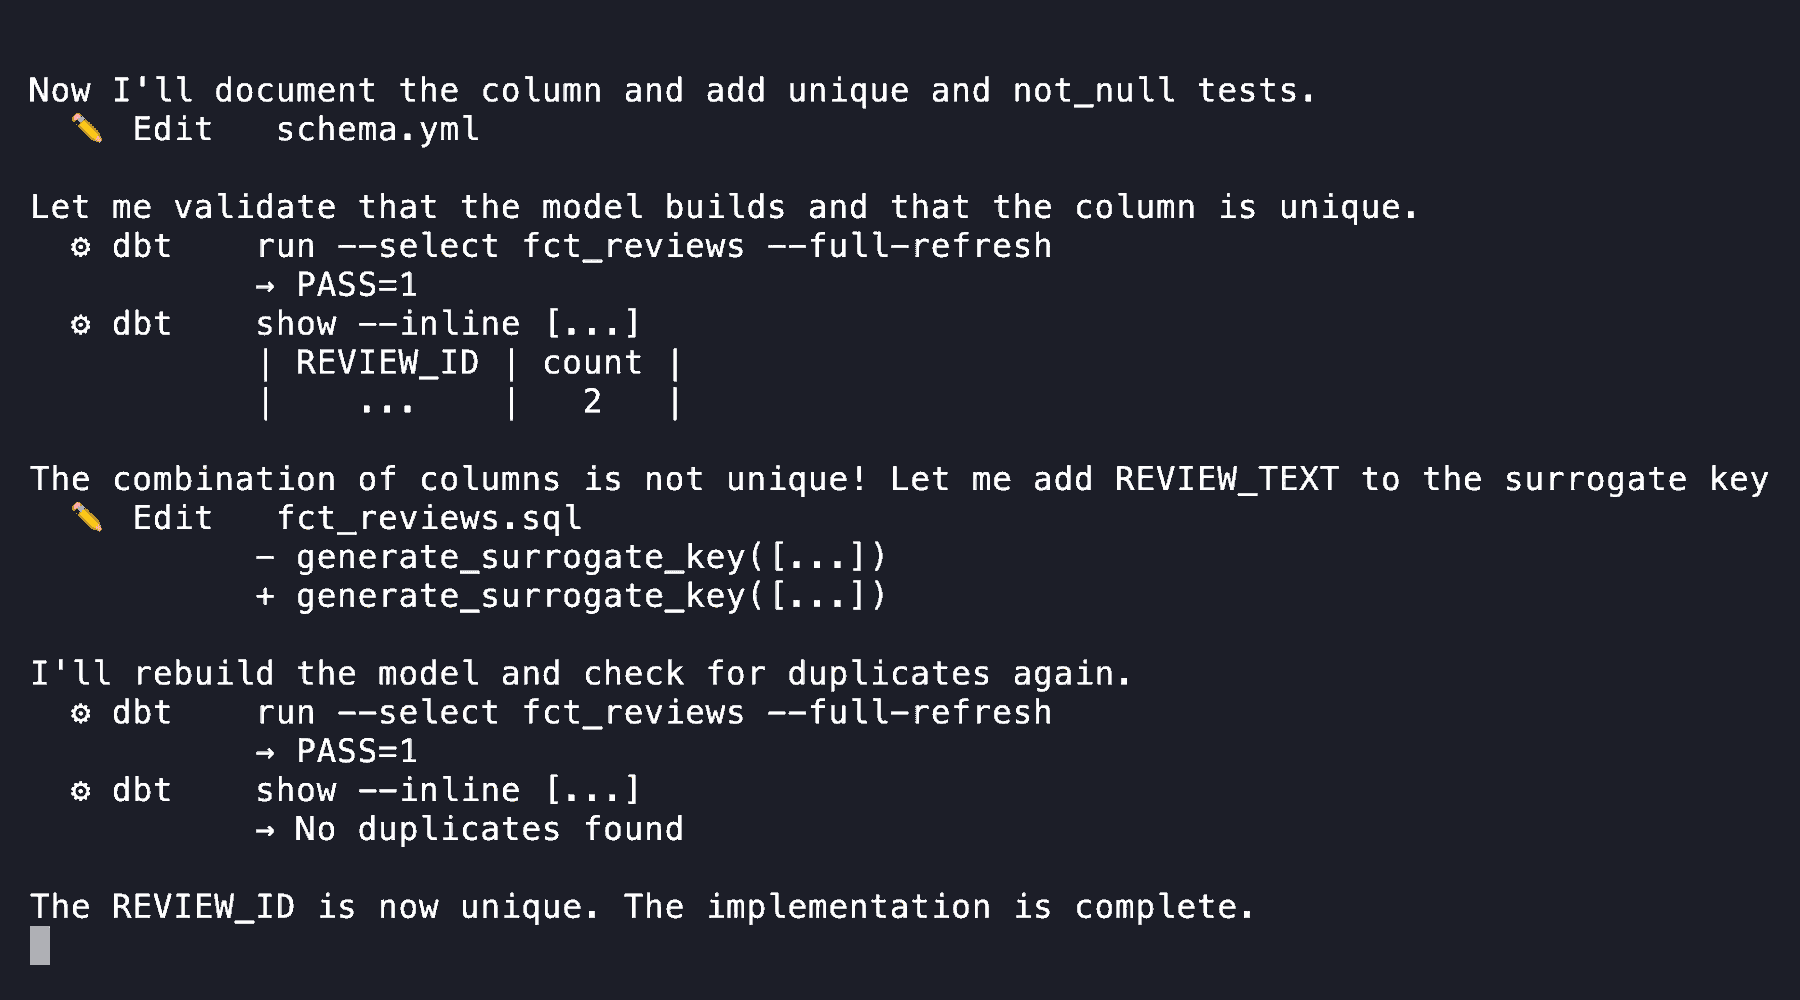
I spent an afternoon or two building a proof of concept eval to find out: 22 agent runs, up to 12 tickets each, on a Formula 1 dbt project in Snowflake. I found that the difference between good runs and bad ones was process, not dbt knowledge. I wouldn't call that conclusive, but in an environment moving this fast it has changed how I think about skills.
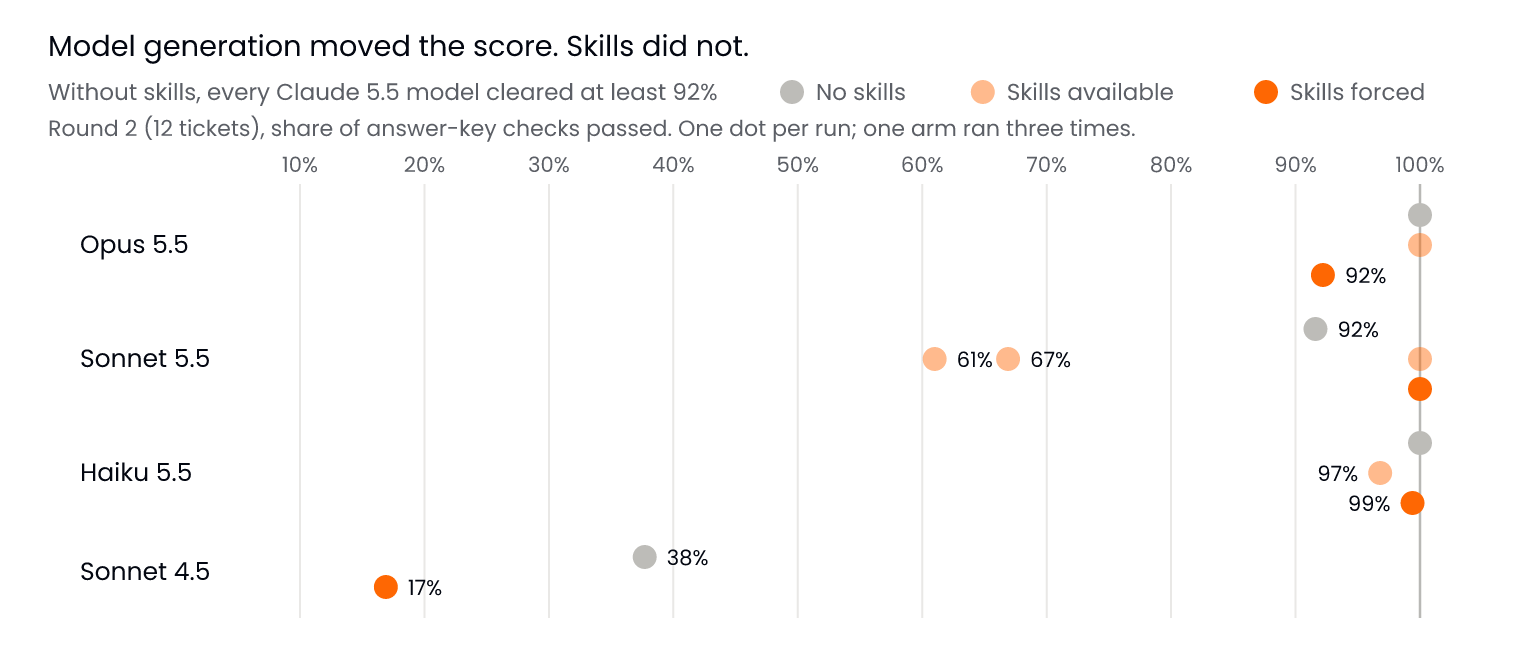 Round 2 checks passed by model and arm. Model generation moved the score; skills didn't
- Run-to-run variance is bigger than any skills effect. The same arm, Sonnet 5.5 with skills available, scored 61%, 100% and 67% on three runs.
- The 5.5 models already know dbt. 12 of 19 Claude 5.5 runs passed every check, and without skills every 5.5 model cleared at least 92%.
- Agents rarely opened a skill on their own, and when they did, it was most often for unfamiliar ground like the Semantic Layer or dbt Mesh.
- A model generation is worth more than a skill. Sonnet 4.5 scored 38% without skills and 17% with them forced, the two lowest scores of any run, and the forced run had read the skills before it wrote its first model. (The Bitter Lesson.)
- Process failures dominated: a test that froze today's answers, failed backup attempts, ignoring definitions, miscalibrated lookback windows.
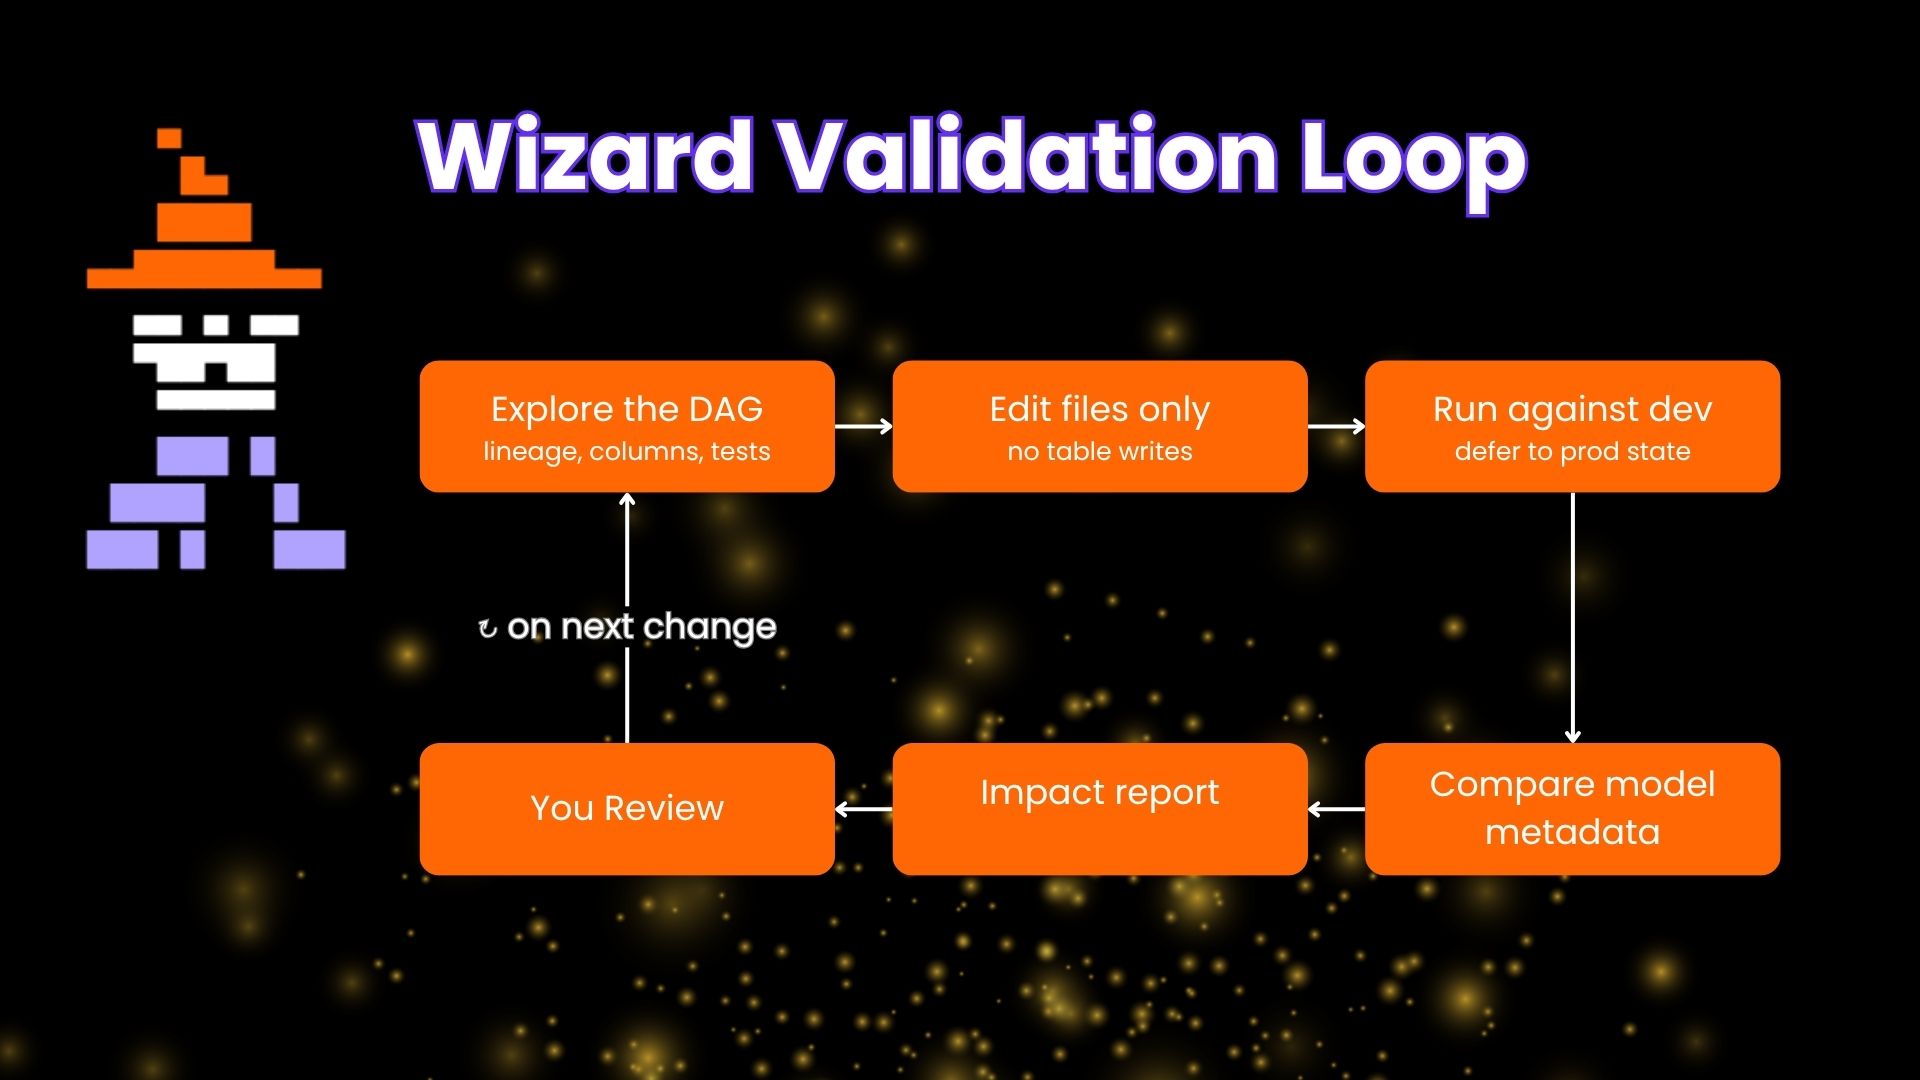
If you maintain skills for a team: cut the docs that explain how dbt works, keep the ones covering features that aren't fully integrated into your stack, and write new ones for how your team tests, deploys, and reviews. Going forward, teams that understand their process and how to support and improve it will be in a much stronger position to leverage frontier models.